Skip to content
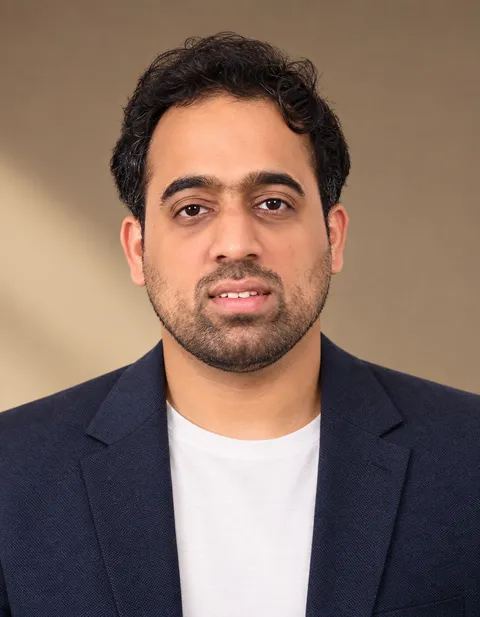
Photo of Sudhesh Prabhu

Data Professional

Hi, I'm Sudhesh Prabhu.

I build data pipelines and cloud data platforms that turn scattered sources into reliable, analytics-ready data.

About

A bit about me

I'm a data professional with 10 years of experience in banking and finance. I'm currently a Data Owner at JPMorgan Chase for Digital Communications, the product that sends more than 5 billion alerts and notifications to customers across the bank.

I work closely with Product Tech, application and Data Technology teams to build pipelines that move data from system-of-record (SOR) application databases into our AWS S3 data lake and on to Snowflake, using CockroachDB, S3, Snowflake and Python. I use GitHub Copilot extensively to automate parts of my day-to-day work, and Claude Code to build my own projects.

Before this I was a data scientist and senior data engineer at JPMorgan Chase, and a data engineer at Tiger Analytics and Wells Fargo, designing and supporting large-scale pipelines on Spark, Hadoop and AWS, and preparing data for analysts and data scientists. I also hold a Post Graduate Certification in Data Science and Engineering from IIIT Bangalore.

Based in Bengaluru, India.
Experience

Where I've worked

Career at a glance · 2016 to today
  • JPMorgan Chase 2022–now
  • Tiger Analytics 2022
  • Wells Fargo 2016–2022
  1. JPMorgan Chase

    Dec 2022 — Present
    1. Data Owner

      Jul 2026 — Present
      • Data owner for Digital Communications, which sends 5B+ alerts and notifications to customers across the bank.
      • Partner with technology teams on pipelines from SOR databases to the S3 data lake and Snowflake.
    2. Data Scientist

      Jan 2025 — Jun 2026
      • Built customer sub-segments for marketing and targeting using K-means and supervised learning.
      • Worked on every step, from building the input datasets to delivering the final segments.
    3. Senior Data Engineer

      Dec 2022 — Dec 2024
      • Built PySpark pipelines on AWS EMR unifying 10+ sources for analytics and customer segmentation.
      • Led the migration of customer data from Hadoop and Teradata to Snowflake.
  2. Tiger Analytics

    Jul 2022 — Nov 2022
    1. Data Engineer

      • Built Spark pipelines on AWS for Lands' End's dynamic promotions application.
  3. Wells Fargo

    Jul 2016 — Jul 2022
    1. Data Engineer

      • Grew from Apps Programmer/Analyst to Data Engineer on the Capital Mortgage Operational Data Store.
      • Built ETL with Ab Initio, Hadoop and Teradata, and provided Level 3 production support.

Skills

What I work with

Big Data

  • Apache Spark (PySpark)
  • Hadoop
  • Hive
  • HDFS
  • Sqoop
  • Airflow

Cloud (AWS)

  • EMR
  • S3
  • Glue
  • Athena
  • Redshift

Data Stores

  • Snowflake
  • CockroachDB
  • Teradata
  • Redshift

Languages & Tools

  • Python
  • SQL
  • UNIX shell
  • Ab Initio
  • GitHub
  • Jenkins
  • CI/CD

AI Tools

  • GitHub Copilot
  • Claude Code

Practices

  • Pipeline design & optimisation
  • Data lake & warehouse architecture
  • Regulatory reporting
  • Agile

Projects

Selected work

All projects →

JPMorgan Chase · Data Owner · 2026

Alerts 2.0 Migration

Migrating the bank's alert preferences application from a legacy platform to Alerts 2.0, including a new database and an entirely new data pipeline.

  • Moved the application from a legacy database to CockroachDB
  • Built a new pipeline from CockroachDB to the AWS S3 data lake and on to Snowflake
  • Coordinated product, technology and data technology teams for a smooth cut-over
  • Involved in every stage of testing
  • CockroachDB
  • AWS S3
  • Snowflake
  • Python
  • Data Migration

Personal project · 2026

Play Chess

A free chess web app: play eight bots powered by Stockfish, review your games, solve puzzles, learn openings and follow live tournaments, all running in the browser.

  • Stockfish running in the browser as WebAssembly, with eight bots from ~400 to full strength
  • Move-by-move game review with accuracy, an evaluation graph and blunder detection
  • 10,000 puzzles and 3,865 openings built from the Lichess open databases
  • FIDE top-100 lists refreshed monthly by an automated data pipeline
  • Next.js
  • TypeScript
  • React
  • Stockfish
  • Vercel
  • Claude Code

JPMorgan Chase · Data Scientist · 2025

Customer Sub-Segmentation

Customer sub-segments for marketing and targeting, built with K-means clustering and supervised learning on secure, enriched datasets.

  • Built the input datasets for clustering with PySpark on AWS EMR
  • Created sub-segments using K-means, followed by supervised learning
  • Enriched customer data with bureau and credit history via Redshift
  • Worked on every step, from raw data to final segments
  • K-means
  • Supervised Learning
  • PySpark
  • AWS EMR
  • Snowflake

JPMorgan Chase · Senior Data Engineer · 2024

Digital Channel Submission Rate

Migrated legacy Hive workflows to an automated PySpark and Airflow pipeline powering Tableau dashboards on digital customer activity.

  • Cut processing time from 12 hours to under 2
  • Replaced manual Hive workflows with PySpark on Hadoop
  • Fully automated scheduling and orchestration with Airflow
  • Fed Snowflake and Tableau for near real-time digital metrics
  • PySpark
  • Hadoop
  • Airflow
  • Snowflake
  • Tableau

Education

Learning & credentials

  • Post Graduate Certification in Data Science and Engineering

    Jan 2024 — Feb 2025

    IIIT Bangalore · CGPA 3.7/4

  • B.E. in Computer Science and Engineering

    Aug 2012 — Jul 2016

    R.V. College of Engineering, Bangalore · CGPA 8.8/10

Certifications

  • AWS Certified Data Analytics – Specialty
  • AWS Certified Developer – Associate
  • AWS Certified Cloud Practitioner

Beyond work

Off the clock

Chess

I've always loved the game, so I built play-chess.in to play, solve puzzles and follow the world's top players.

Play a game on play-chess.in ↗

Cricket

A big cricket fan, and a loyal supporter of Royal Challengers Bengaluru (RCB).

Reading

I enjoy reading. My favourite book is The Stranger by Albert Camus.

Contact

Let's work together

I'm open to new roles, collaborations and interesting data engineering problems. The quickest way to reach me is by email.

Email meLinkedInGitHub